In-Game Advertising Measurement: From Exposure to Outcomes
·17 min read
ROLearn's five-dimension assessment framework for determining whether a Roblox, Fortnite or virtual-world campaign has evidence strong enough to support reporting, comparison and budget decisions.
By Tu Dang · Founder of ROLearn
· 14 min read · Updated
A polished leaderboard can create confidence faster than the evidence deserves. Five brand categories, five blue bars and one neat winner look like research. But unless every campaign was measured against a common objective, population, window, cost boundary and outcome design, the ranking compares reporting systems as much as it compares performance.
Public virtual-world case studies rarely disclose all of those conditions. One may report visits, another average session time, another item claims and another brand lift. Media support, geography, age eligibility, activation duration and return windows often differ. Adding those figures to a single score would create precision, not comparability.
The ROLearn 2026 Virtual-World Activation Measurement Readiness Index therefore answers the question that comes first: is the evidence ready to support the decision a brand wants to make? It is ROLearn’s assessment framework for Roblox brand activations, Fortnite campaigns and other immersive marketing programs. It is not an industry standard, certification or ranking of beauty, fashion, entertainment, retail or sports brands.
A performance number should not become more confident as it moves farther from the evidence that produced it.
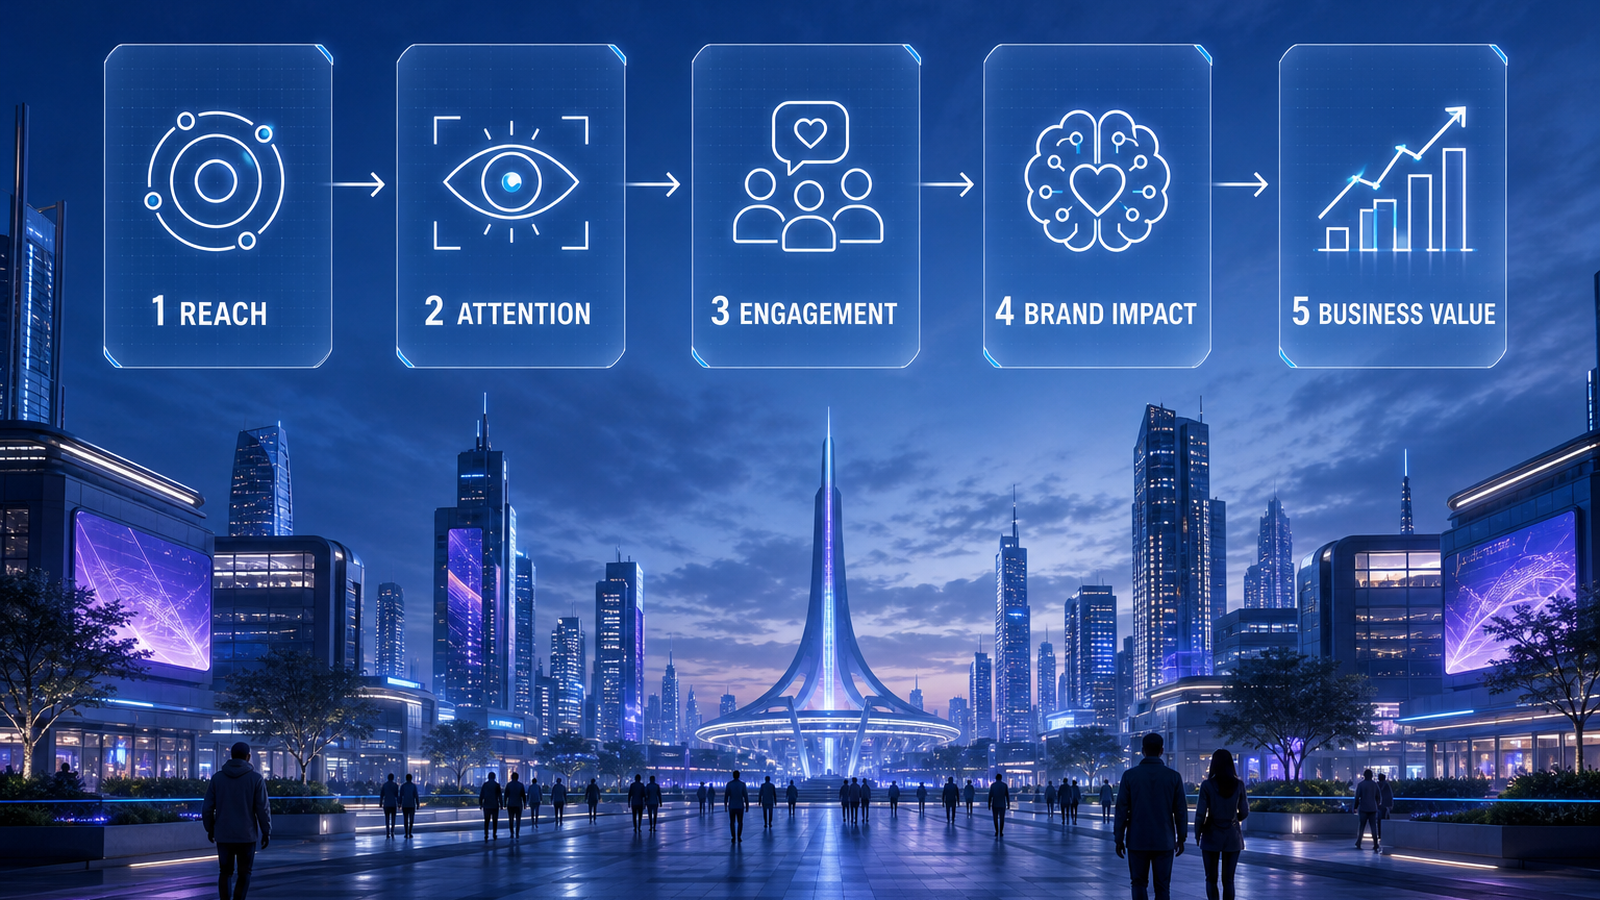
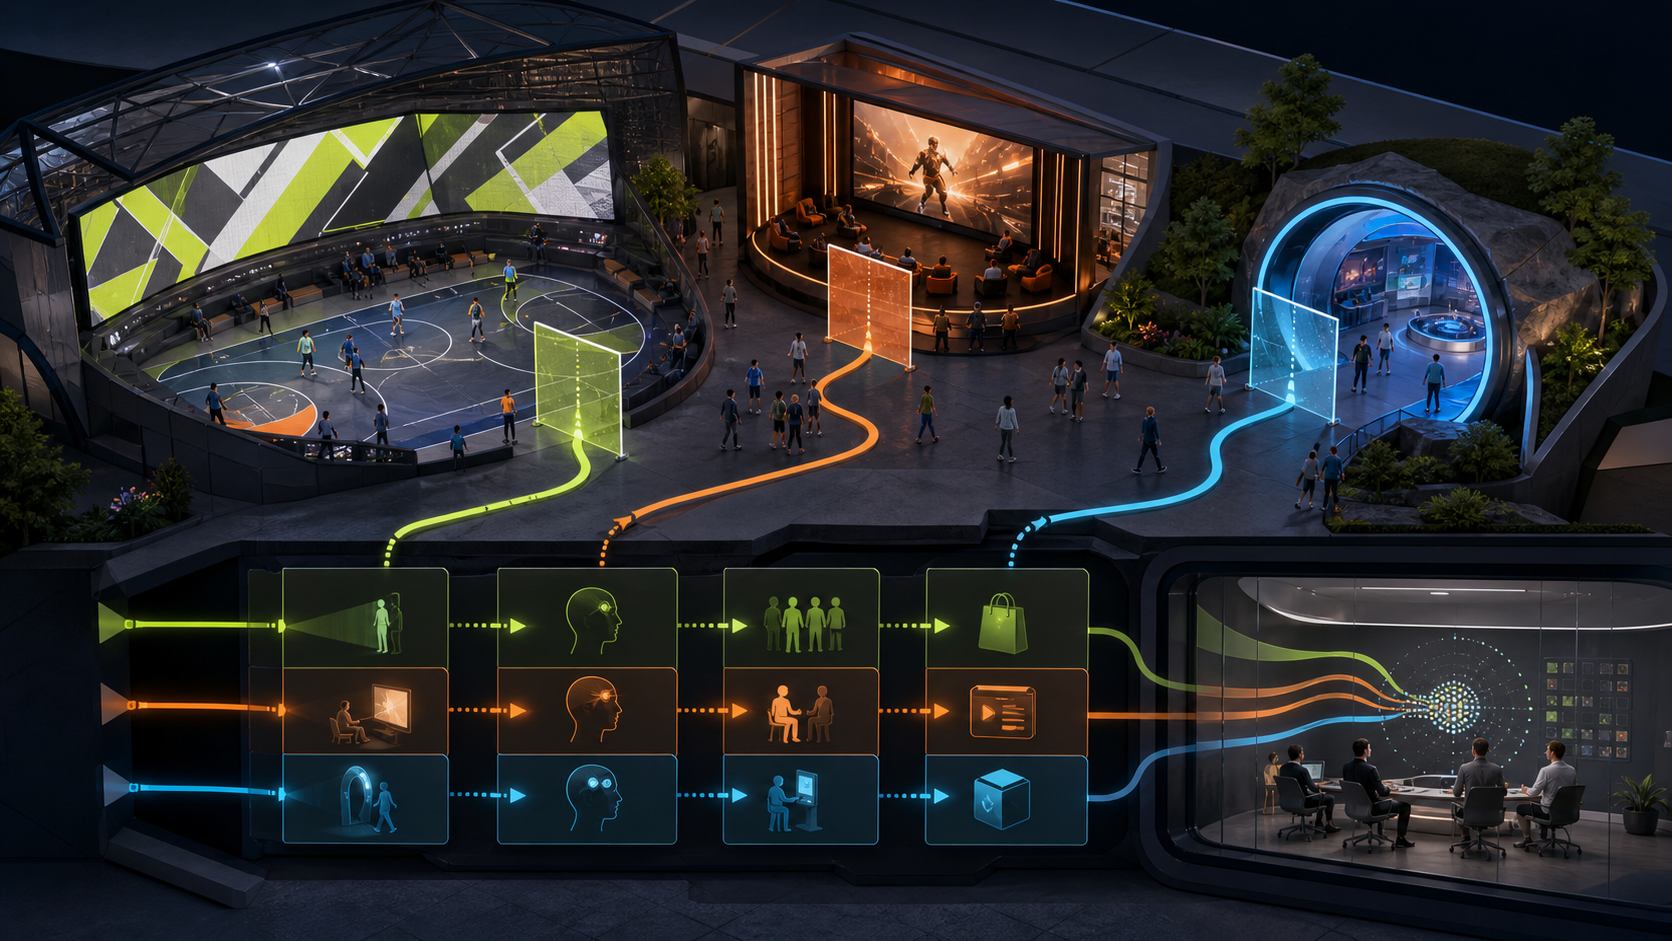
Comparing brand activations is harder than comparing display campaigns because the activation can be a game, event, persistent world, creator integration, virtual item, media placement or a combination of them. The player does not follow a single linear funnel, and the program’s effects may travel through platform discovery, friends, creators, social video and press.
Even familiar metrics change meaning with their denominator. A visit may mean a loaded session or an active player. Session time can be reported per session or per person. Retention can refer to a cohort’s return on a specific day or at any point during a window. A social view is an opportunity to see a video, not a unique addition to in-world reach. Brand lift is a difference between measured groups, not another engagement count.
The primary sources reinforce these boundaries. Roblox separates acquisition, engagement, retention and monetization and reports source-level cohort measures. Epic separates audience, gameplay, engagement, satisfaction and retention in Fortnite Project Analytics and warns that summing daily active players duplicates people. IAB distinguishes baseline and additional metrics by gaming ad format. MRC requires delivery and exposure quality before outcome attribution becomes actionable. WFA’s Halo work exists because cross-media reach and frequency need privacy-aware deduplication rather than simple addition.
Those systems provide useful pieces. None makes five unrelated public case studies a controlled performance benchmark.
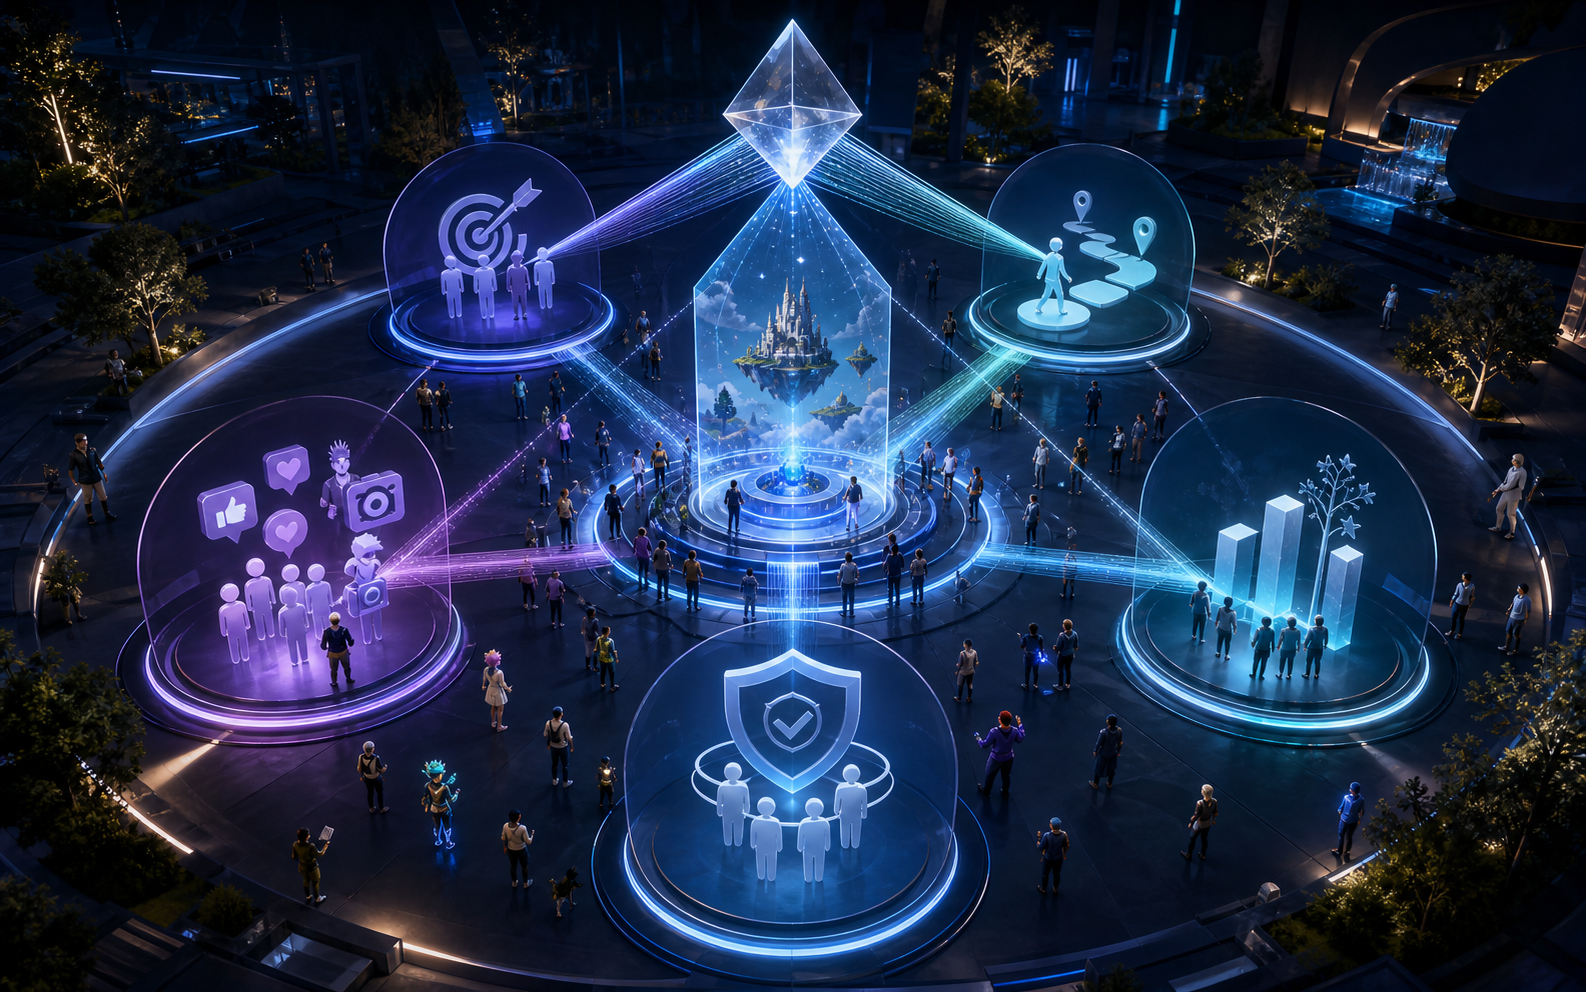
The Index evaluates the strength of the measurement system across five dimensions. Each answers a question that a procurement lead, CMO, studio head or finance team should be able to interrogate.
The Index does not reward the largest number. It rewards the evidence needed to interpret whatever number the campaign produces. A small, well-designed study can be more decision-ready than a huge launch with no stable denominator or outcome comparison.
| Dimension | Question | Minimum decision-grade evidence | Common failure |
|---|---|---|---|
| Objective integrity | What decision and outcome were defined before results? | Population, primary outcome, window and decision rule | Metric shopping after launch |
| Player-journey instrumentation | What did qualified players actually do over time? | Validated acquisition, active behavior, meaningful action and cohort return | Treating visits as engagement |
| Outcome design | What changed beyond activity? | Appropriate attention, brand or business measure with a credible comparison | Calling correlation impact |
| Cross-channel reconciliation | How did the activation travel outside the world? | Native channel measures, common windows and an explicit overlap policy | Adding audiences and views |
| Governance and reproducibility | Can another qualified analyst reproduce the claim? | Versioned definitions, quality controls, exclusions and uncertainty | A number with no lineage |
Every dimension receives the highest level for which all required conditions are met. Teams should not award partial credit for an undocumented assumption.
| Level | Name | What it means |
|---|---|---|
| 0 | Unmeasurable | The objective, event, denominator or source is absent or cannot be verified. |
| 1 | Instrumented | Relevant signals are collected, but definitions, validation or decision logic remain incomplete. |
| 2 | Reportable | Definitions, denominators, windows, ownership and material limitations are documented. |
| 3 | Decision-grade | Evidence is validated and connected to a pre-defined operating or investment decision with an appropriate comparison. |
| 4 | Auditable | Methods, versions, controls, transformations and uncertainty are reproducible by an independent qualified reviewer. |
The total ranges from 0 to 20, but the profile matters more than the sum. Two campaigns can both score 14 while carrying very different risks. One may have excellent telemetry and weak outcome evidence. The other may have a strong brand study but incomplete cross-channel coverage.
Measurement begins with the decision, not the dashboard. A credible brief names the audience, geography, activation period, primary outcome and smallest change that matters. It identifies what the team will continue, change or stop when the result arrives.
At level 1, the team has KPIs but no explicit decision rule. At level 2, it has a documented measurement brief. Level 3 requires the outcome and comparison design to be fixed before results are reviewed. Level 4 adds approval history, change control and enough detail for an independent analyst to recreate the brief.
The counterfactual belongs here. If the intended claim is incremental brand lift, action or sales, the team must state what would likely have happened without the activation. That may require randomized assignment, a matched control, a credible pre-period design or another defended method. A before-and- after spike without a comparison remains descriptive.
If the primary outcome changes after results are known, the evidence cannot receive a decision-grade rating.
Roblox analytics can show acquisition sources, play-through rate, session time, retention and downstream cohort measures such as playtime and revenue per user. Fortnite Project Analytics separates impressions and clicks from active players, playtime, new and returning players and classic retention. These are strong behavioral signals when the team has the required permissions and stable event definitions.
They still need an activation-specific journey. Define a qualified participant, the first meaningful action, the intended depth event and the relevant return cohort. Record the experience version a player encountered. Validate that events fire once, timestamps use the correct zone, idle time is treated consistently and client failures do not silently disappear.
At level 1, counters exist. Level 2 requires a documented event dictionary, denominators, sources and cohort rules. Level 3 requires tested completeness and an objective-linked funnel. Level 4 adds reproducible queries, change logs, quality thresholds and retained snapshots.
Visits do not receive extra weight merely because they are large. They establish arrival. Active play, meaningful choice, social participation and return answer different questions and remain separate.
Platform behavior can show what a player did. It cannot, on its own, establish that the player consciously noticed the brand, remembered it, changed preference or made an incremental purchase.
Outcome design selects the method that matches the claim. Attention may combine active presence in a branded context with direct or validated attention methods. Brand outcomes may require exposed and comparison groups, a properly specified instrument, sample-quality checks and uncertainty. Business outcomes require a defined conversion, attribution window, cost boundary and, for causal language, a credible counterfactual.
Roblox currently presents third-party measurement options covering audience verification, incrementality and business outcomes. That is useful evidence of the measurement categories available, not proof that every branded experience automatically produces those outcomes.
At level 2, the campaign can report a defined outcome with its method and limitations. Level 3 requires an appropriate comparison and a sample capable of supporting the intended decision. Level 4 requires reproducible processing, documented quality controls, uncertainty and sensitivity analysis where modeling matters.
A virtual-world activation can generate creator videos, social conversation, livestreams and press. Those channels should be measured in their native units before any comparison: people reached, valid views, watch time, interactions, article readership estimates, link traffic and outcome evidence.
Do not add the audiences. The same person can visit the experience, watch a creator, see a short video and read an article. Exact person-level matching is usually incomplete and may be inappropriate. A credible report uses direct deduplication where lawful and available, modeled overlap where defensible and a range where neither is complete.
At level 1, the campaign has mentions and view counts. Level 2 requires channel- specific definitions, a common campaign window and a documented discovery protocol. Level 3 requires an overlap policy, source-quality controls and traceable campaign identifiers. Level 4 requires reproducible collection, privacy-aware reconciliation, coverage analysis and sensitivity ranges.
WFA’s Halo framework is instructive because it treats cross-media deduplicated reach and frequency as an architecture that must combine data under privacy controls. Halo is not a ready-made universal currency, and neither is the Index.
The last dimension determines whether the first four can survive scrutiny. Governance records who owns each source, which definitions were used, when data was extracted, how invalid activity and missingness were handled and which assumptions can materially change the result.
Every executive claim should link to an evidence ledger containing:
At level 2, those fields are documented. Level 3 adds independent checks and a frozen reporting specification. Level 4 requires reproducible queries or models, review history, controlled access and retained evidence sufficient for an audit.
NIST guidance on uncertainty is written for measurement science rather than marketing, but its discipline applies: report the result and its uncertainty, state how the interval was obtained and avoid implying a probability interpretation the method cannot support.
The arithmetic is deliberately simple:
Readiness total = the five dimension levels added together, from 0 to 20.
The total maps to a descriptive band.
| Total | Band | Permitted interpretation |
|---|---|---|
| 0-4 | Fragile | Material evidence foundations are missing. Use results for orientation only. |
| 5-8 | Instrumented | Useful signals exist, but the campaign is not ready for comparative or outcome claims. |
| 9-12 | Reportable | Descriptive reporting is supportable under the documented definitions and limits. |
| 13-16 | Decision-grade | Evidence can support the stated management decision if no dimension is below level 2. |
| 17-20 | Auditable | Evidence is highly reproducible if no dimension is below level 3. |
The gates matter. A total of 15 cannot be called decision-grade if outcome design is level 1. A total of 18 cannot be called auditable if cross-channel reconciliation is level 2. In each case, report the numeric total, the five-part profile, the gated band and the blocking dimension.
This prevents strong player telemetry from laundering a weak causal claim. It also prevents a sophisticated brand-lift study from concealing unreliable exposure data.
At procurement, put the five dimensions into the statement of work. Require data access, event ownership, outcome design, external-media coverage and documentation before selecting a partner. Ask suppliers to identify which evidence will be observed, which will be modeled and which will remain unavailable.
Before production, complete a provisional score. Every level below 2 becomes a design task, not a caveat saved for the final report. Instrumentation and study recruitment are cheaper to solve before launch than after the exposure window has closed.
During launch, monitor data quality and experience health rather than chasing the composite total. Check event completeness, loading failures, early exits, invalid activity, sample balance and version changes. A readiness rating should fall if the evidence system degrades.
After the campaign, freeze the evidence set, complete the rating and place it beside the results. Compare performance only among campaigns with compatible objectives, populations, definitions, windows and readiness profiles.
Award a level only when every required condition is documented in the campaign record.
Score each dimension independently from 0 to 4, then calculate the 0-to-20 total.
Cap the band when a critical dimension falls below the minimum for decision-grade or auditable use.
Publish the total, five-part profile, gated band, assessment date and largest limitation together.
The 12 August 2026 edition removed all illustrative category scores from the original site scaffold. No category or campaign performance data is claimed in this report.
The Index and OMNI-EMV’s earned media value architecture do different jobs.
The Index assesses whether an activation’s evidence architecture is mature enough to support a claim. OMNI-EMV is ROLearn’s framework for valuing earned attention across virtual-world participation, creators, social media and press. A campaign should not enter an OMNI-EMV analysis simply because it generated many visible counters. It should first demonstrate that its channel inputs, quality controls, relevance, sentiment, overlap and uncertainty are fit for use.
The Index does not disclose or approximate OMNI-EMV’s proprietary rates, weights, thresholds or coefficients. It also does not calculate media value, revenue, profit or ROI. Its role is to expose whether the evidence beneath those numbers is strong, weak or missing.
The evidence definitions behind that assessment are maintained in ROLearn’s virtual-world measurement source tracker, which links each source class to its current primary documentation.
The Index is a structured ROLearn assessment framework, not an industry standard or certification. Its rubric is informed by primary measurement frameworks, but IAB, MRC, WFA, AMEC, Roblox, Epic and NIST have not endorsed ROLearn’s levels or bands.
Readiness is not performance. A well-measured campaign can underperform, and a poorly measured campaign can create real value that the available evidence cannot demonstrate. The Index should never be used to imply that a high score caused strong outcomes.
Nor does readiness erase context. A Fortnite island designed for long-term retention should not be judged against a one-night Roblox event merely because both have an auditable profile. Compatible objectives and definitions remain the price of comparison.
| Use the Index to | Do not use the Index to |
|---|---|
| Specify measurement requirements before production | Rank brand categories without a comparable dataset |
| Find the evidence gap that can invalidate a claim | Turn visits, views and articles into one audience total |
| Qualify campaigns before benchmarking performance | Claim brand lift, incrementality or ROI from platform behavior alone |
| Compare suppliers under a common evidence framework | Reward whichever supplier reports the largest counters |
| Show decision-makers how much confidence a result deserves | Hide weak dimensions behind a strong composite total |
The useful output is not a glamorous league table. It is a defensible answer to a harder question: what can this campaign’s evidence actually support?
Once that answer is visible, brands, agencies and game studios can compare like with like, invest in the missing measurement before it is too late and carry the result into a budget decision without deleting the conditions that make it true.
Spotted an error? How we handle corrections.
Tu Dang. "Virtual-World Activation Measurement Readiness Index 2026." ROLearn Intelligence, July 25, 2026. https://intelligence.rolearn.dev/reports/virtual-world-activation-measurement-readiness-index-2026

Tu Dang
Founder of ROLearn
I study how games become businesses, media channels, and virtual economies.
View author profile →One decisive insight on games, brands, and virtual worlds, every Thursday.
Tu Dang
Founder of ROLearn
I study how games become businesses, media channels, and virtual economies.
One decisive insight on games, brands, and virtual worlds, every Thursday.